

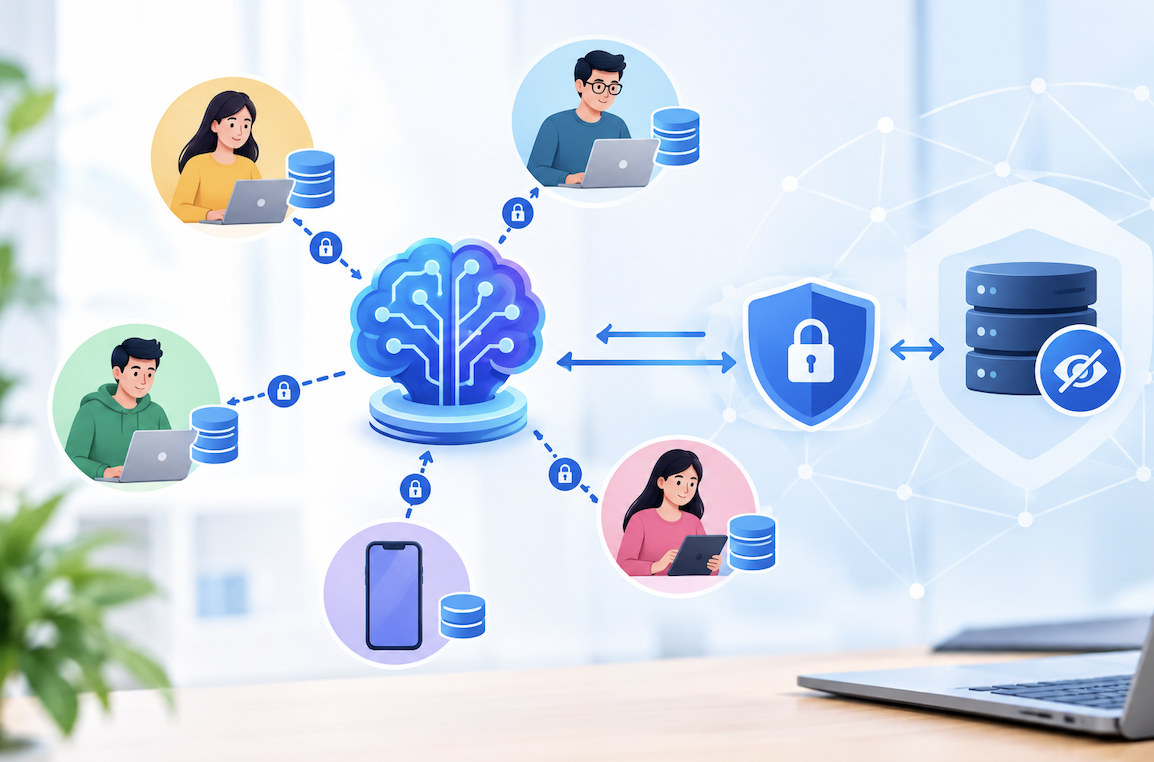
Training an effective AI model traditionally required gathering enormous amounts of data into one central location, a process that works well for public information but creates genuine privacy concerns when that data includes sensitive personal details like medical records, financial transactions, or private messages. Federated learning offers a fundamentally different approach, training models directly on distributed devices without ever centralizing the underlying raw, sensitive data at all.
This technique has attracted particular interest from privacy-conscious industries and technology companies seeking to build genuinely useful AI capabilities without accumulating the kind of centralized, sensitive data repositories that have become increasingly attractive targets for both regulators and malicious attackers alike.
Understanding the Core Concept Behind This Approach
Federated learning trains a shared AI model across many separate devices or servers, each holding its own local data, without that raw data ever leaving its original location or getting transmitted anywhere else. Instead of sending data to a central server, the model itself travels to where the data already lives, learns from that local data, and sends back only the resulting learned improvements, not the underlying raw data itself.
A central server then combines these individual learned improvements from many different participating devices, gradually refining a shared model that benefits from the collective knowledge across the entire distributed network of devices, all without any single participant’s raw, potentially sensitive data ever having been centrally collected or exposed to any other party in the process.
The Basic Flow of a Federated Learning Process
- A central server distributes a current version of the shared model to participating devices
- Each device trains that model locally, using only data stored on that specific device
- Devices send back only their learned model updates, never the underlying raw data
- The central server aggregates these updates to improve the shared, collective model
Why This Approach Differs Fundamentally From Traditional AI Training
Traditional machine learning approaches typically require centralizing training data into one location, a data center or cloud storage system, where the actual model training then occurs. This centralization creates a single point of both technical and legal exposure, since a breach at that central location could expose the sensitive personal data belonging to every single individual whose information contributed to the training dataset.
Federated learning avoids this centralization risk entirely by design, since sensitive data never leaves its original device or location in the first place. Even if the central server coordinating the learning process were somehow compromised, an attacker would only gain access to aggregated, abstracted model updates rather than any individual’s actual raw, sensitive underlying data.
- Traditional approaches centralize potentially sensitive data into one exposed location
- Centralization creates a single point of failure for both technical and legal exposure
- Federated learning avoids this risk since raw data never leaves its original device
- Compromising the central coordinator wouldn’t expose any individual’s actual raw data
Real Applications Already Using This Privacy-Preserving Technique
Smartphone keyboard prediction represents one of the most widely deployed, if invisible, applications of federated learning, where phones collectively improve text prediction accuracy by learning from how millions of users actually type, without any individual’s specific private messages ever leaving their own personal device. This allows the collective system to genuinely improve over time while respecting individual message privacy throughout the entire ongoing process.
Healthcare research has begun exploring federated learning specifically for training diagnostic AI models across multiple hospitals without requiring those hospitals to share actual patient records with each other or with any external, third-party organization. This approach allows AI models to potentially benefit from a much larger and more diverse combined dataset than any single hospital alone could ever provide, while still respecting strict patient privacy requirements and hospital-specific data governance policies.
- Smartphone keyboard prediction improving collectively without exposing individual messages
- Healthcare diagnostic models training across hospitals without directly sharing patient records
- Financial fraud detection systems learning across institutions without sharing customer transaction data
- Autonomous vehicle systems improving collectively without centralizing individual driving data
A Concrete Example From Healthcare Collaboration
Consider several hospitals across different regions wanting to collaboratively build a more accurate AI model for detecting a rare medical condition from imaging scans, a task that benefits enormously from a larger, more diverse training dataset than any single hospital’s own patient population could provide alone. Directly sharing actual patient scans between these hospitals would raise serious privacy concerns and likely violate healthcare privacy regulations in most jurisdictions.
Using federated learning instead, each hospital trains the shared model locally using their own patient scans, without those actual scans ever leaving that hospital’s own secure systems. Only the resulting learned model improvements get shared and combined centrally, allowing all participating hospitals to collectively benefit from a considerably more accurate, robust diagnostic model than any single institution’s smaller, more limited dataset could have realistically produced independently on its own.
Technical Challenges This Approach Introduces
Coordinating training across many distributed devices, each with potentially different computing capabilities, network connectivity, and data characteristics, introduces genuine technical complexity that centralized training approaches simply don’t need to address at all. Some devices might have slow or intermittent internet connections, requiring the overall system to handle participants dropping in and out unpredictably throughout an ongoing training process.
Data across different participating devices also often varies considerably in both quantity and characteristics, a challenge researchers call non-identically distributed data, which can make training a genuinely accurate, well-balanced shared model considerably more complicated than training on a carefully curated, centrally controlled dataset would typically be. Researchers continue actively developing techniques specifically to address these persistent coordination and data variation challenges.
- Coordinating unpredictable, intermittent device connectivity adds genuine technical complexity
- Variation in data characteristics across devices complicates achieving balanced, accurate training
- Communication overhead between devices and the central coordinator can become substantial
- Ongoing research continues developing solutions to these persistent coordination challenges
Privacy Limitations That Still Deserve Careful Consideration
While federated learning meaningfully improves privacy compared to centralized data collection, it doesn’t provide absolute, complete privacy protection on its own. Researchers have demonstrated that, under certain specific conditions, it’s sometimes theoretically possible to infer information about the underlying training data by carefully analyzing the model updates being shared, even without direct access to that raw underlying data itself.
Additional privacy-enhancing techniques, such as differential privacy, which deliberately introduces carefully calibrated statistical noise into shared updates, are often combined with federated learning to provide stronger, more robust privacy guarantees against these more sophisticated inference attacks. Understanding that federated learning represents a meaningful privacy improvement rather than an absolute, mathematically perfect privacy guarantee helps set appropriately realistic expectations for anyone evaluating or implementing this technology.
- Federated learning improves but doesn’t provide absolute, complete privacy protection alone
- Sophisticated analysis can sometimes theoretically infer information from shared model updates
- Differential privacy techniques are often combined with federated learning for stronger protection
- Realistic expectations matter when evaluating this technology’s actual privacy guarantees
Comparing Federated Learning to Other Privacy-Preserving Approaches
Federated learning represents just one approach within a broader family of privacy-preserving machine learning techniques, and understanding how it relates to alternatives helps clarify when it genuinely represents the best fit for a given situation. Homomorphic encryption, another technique in this space, allows computation directly on encrypted data without ever decrypting it, offering strong privacy guarantees but typically at a significant computational performance cost compared to federated learning’s more practical, everyday efficiency.
Secure multi-party computation, yet another related approach, allows multiple parties to jointly compute a result without revealing their individual inputs to each other, sharing some conceptual similarity with federated learning’s collaborative structure. Organizations often choose between these approaches based on their specific performance requirements, the sensitivity of their particular data, and the practical constraints of their existing technical infrastructure and team expertise.
- Homomorphic encryption offers strong privacy but at significant computational cost
- Secure multi-party computation shares conceptual similarities with federated learning
- Choosing between these approaches depends on performance needs and data sensitivity
- No single technique represents a universal best choice across every possible scenario
Ongoing Research Directions Shaping This Field’s Future
Researchers continue actively working to address federated learning’s remaining technical challenges, including developing more efficient communication protocols that reduce the bandwidth required to coordinate training across many distributed devices. Improvements in handling non-identically distributed data across participants, along with more robust techniques for detecting and mitigating potentially malicious participants attempting to corrupt the shared model, represent additional active areas of ongoing academic and industry research investment.
Personalization within federated learning frameworks has also attracted growing research interest, exploring how a shared global model might be further customized for individual devices or users without requiring entirely separate training processes for each one. This direction could eventually allow federated learning to deliver both the privacy benefits of distributed training and the accuracy benefits of models tailored to individual user contexts and preferences.
- More efficient communication protocols continue reducing coordination overhead
- Techniques for handling data variation across participants keep improving steadily
- Detecting and mitigating malicious participants remains an active research priority
- Personalization research aims to combine privacy benefits with individually tailored accuracy
Real-World Deployment Considerations Beyond the Research Stage
Moving federated learning from research demonstrations into genuine, reliable production deployment introduces practical engineering challenges that academic papers don’t always fully address. Building robust systems that gracefully handle millions of participating devices with wildly varying connectivity, battery life, and processing capability requires substantial engineering investment beyond the core algorithmic research that initially demonstrates a technique’s theoretical viability.
Organizations that have successfully deployed federated learning at meaningful scale typically emphasize that production engineering challenges, rather than algorithmic limitations alone, often represent the more significant practical barrier to broader adoption. This distinction matters for organizations evaluating federated learning, since technical feasibility demonstrated in a research paper doesn’t automatically translate into straightforward, reliable production deployment without genuine, dedicated engineering effort.
- Production deployment introduces engineering challenges beyond core algorithmic research
- Handling millions of devices with varying connectivity requires substantial engineering investment
- Production engineering often represents a more significant barrier than algorithmic limitations
- Research feasibility doesn’t automatically translate into straightforward production reliability
Industries and Companies Investing Heavily in This Approach
Major technology companies building products that process sensitive personal data across millions of user devices have invested substantially in federated learning research and practical implementation, recognizing both the genuine privacy benefits and the growing regulatory pressure around centralized data collection practices more broadly. This investment has accelerated considerably as data privacy regulations have grown stricter across multiple major global markets.
Beyond large technology companies, industries handling particularly sensitive data, healthcare, finance, and government services, have shown especially strong interest in federated learning as a way to benefit from AI’s genuine capabilities while still satisfying strict, often legally mandated privacy and data governance requirements that would otherwise make centralized AI training approaches genuinely impractical or outright legally impossible in these specific, heavily regulated contexts.
- Major technology companies have invested substantially in this research area
- Growing data privacy regulations have accelerated interest and adoption considerably
- Healthcare, finance, and government sectors show particularly strong interest and investment
- This approach enables AI benefits in contexts where centralized training would be impractical
Final Thoughts
Federated learning represents a genuinely meaningful shift in how AI models can be trained, offering a practical path toward building capable, useful systems without requiring the kind of centralized, sensitive data collection that has become an increasingly significant privacy and security concern. As both privacy regulations and public awareness around data protection continue growing, this collaborative, privacy-preserving approach to machine learning looks likely to play an increasingly important role across genuinely sensitive data domains going forward.
Frequently Asked Questions
1. Does federated learning mean my personal data never gets analyzed at all?
Your data still gets analyzed locally on your own device to help train the model, but the raw data itself never leaves that device or gets shared with any external party.
2. Is federated learning slower than traditional centralized AI training?
It can introduce additional coordination overhead across distributed devices, though ongoing technical improvements continue narrowing this performance gap compared to centralized approaches over time.
3. Can federated learning completely replace traditional centralized AI training?
Not universally; it works particularly well for scenarios involving sensitive, distributed data, though centralized training remains more straightforward and often more practical for less sensitive applications.
4. Do all smartphone apps use federated learning for their AI features?
No, this technique requires specific technical implementation, and while some major technology companies have adopted it for certain features, many applications still rely on traditional, centralized training approaches.
5. Is federated learning considered a fully mature, widely proven technology?
It has moved beyond purely experimental research into genuine production use by major companies, though active research continues addressing remaining technical and privacy-related challenges within the field.
6. Does federated learning require specialized hardware on user devices?
Modern smartphones and computers generally have sufficient processing capability for federated learning’s local training requirements, though very resource-intensive models may still require more capable, higher-end devices.
7. How do researchers measure whether a federated learning model is performing well?
Researchers typically evaluate the aggregated model’s accuracy on held-out test data, similar to traditional machine learning evaluation, while also monitoring for fairness across different participating devices.
8. Could federated learning eventually become the standard default approach for AI training?
For applications involving sensitive, distributed data, many researchers expect growing adoption, though centralized training will likely remain standard for applications without significant privacy considerations.